AI & Cloud Insight
Field notes from building production AI — agents, knowledge systems, and the infrastructure that keeps them honest.
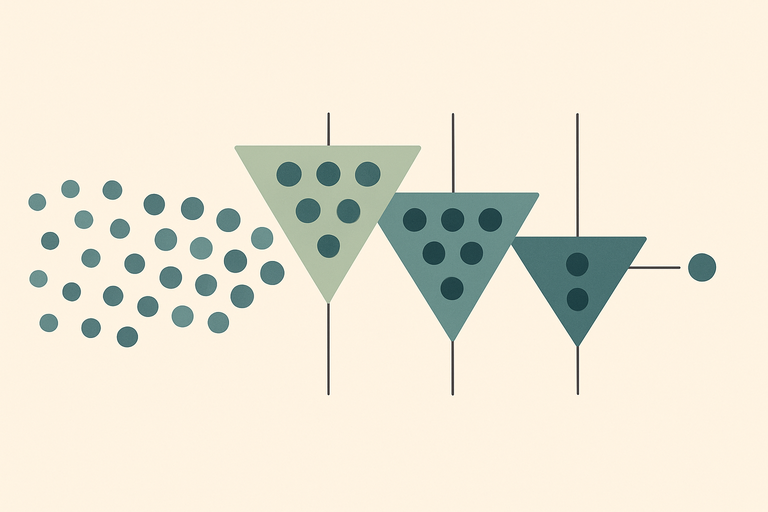
Ten Percent of Ten Percent: Why Independent Checks Beat Better Prompts
You will not prompt a language model step to zero errors, and the last few points cost more than everything before them. What works is a second check that fails differently from the first: 10% x 10% = 1%, but only when the layers are genuinely independent. Five kinds of layer we use in production (reviewer agents that cannot see the author's reasoning, deterministic CI gates, structural guards, blind evaluation against held-out truth, and a human who sees the one percent), one chain from agent-written code to production, the incident that taught us to add an orthogonal layer instead of strengthening the one that missed, and what every layer costs.
Read Article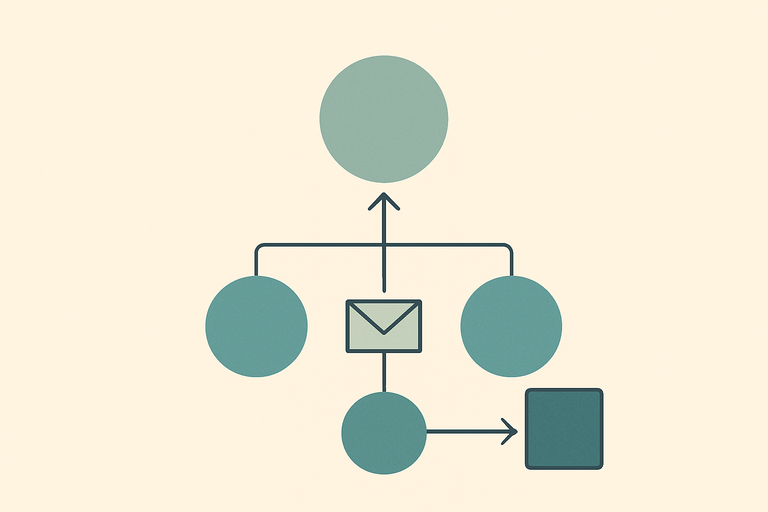
Up, Sideways, Out: Giving an Agent Fleet an Org Chart
Three of our monitoring agents spent a week investigating the same incident without knowing it, because the only channel between them was a thirty-minute message queue and they sleep for hours at a time. The week we finished the three channels an agent org chart actually needs — severity-gated escalation upward, durable peer messaging sideways, and commissioned work outward — and what the fleet did with them in its first 48 hours: 28 messages, 10 threads, one week-old incident split into lanes in a single exchange, and a fix commissioned, shipped, and verified by four agents with one human at the merge.
Read Article