AI & Cloud Insight
Field notes from building production AI — agents, knowledge systems, and the infrastructure that keeps them honest.
The Arcade That Builds Itself: Three Hundred AI-Built Games as a Test Bed for Autonomous Agents
A visitor types one paragraph. A few minutes later an agent on its own machine has written a game, played it in a real browser at desktop and phone size, and shipped it as a single HTML file that makes no network requests. We built Whimcade to find out what our build agents do when nobody is watching and the people judging the output are players, not clients: how the rules travel with each job, why the agent's own test pass beat an independent checker, why we parked an expensive QA stage, and what three hundred games taught us about enterprise agents.
Read Article
Watching the Agent Walk: What a Small Model Does With a Knowledge Graph When You Can See Every Step
A ranked list tells you what retrieval returned. It does not tell you what the agent did with it. So we built a tab where a small model works a question against one bank in public: every search, every entry it reads, every pointer it follows and every walk it takes, painted onto the graph as it happens, with the answer and its citations at the end. The first real runs showed what no benchmark had: the model never walked, it read instead of hopping, and the one pointer it followed went into the answer.
Read Article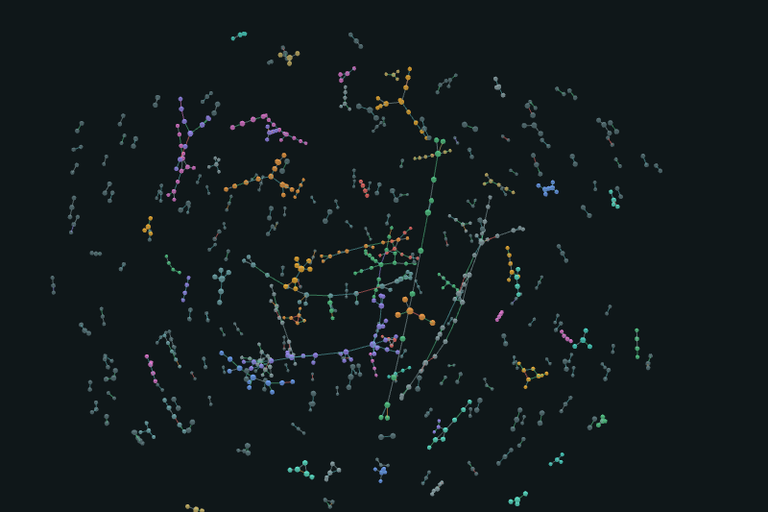
Folding the Graph: How Our Knowledge Bank Learned to Hand Agents the Hop
Semantic search over a shared memory has a quiet failure: the knowledge an agent needs is often one hop away from what the query matched, and a flat top-k has no way to say so. We gave the Knowledge Bank a graph layer that agents write as they work, then taught retrieval to fold connected results into one slot and hand the agent the hop. In the lab, pointers took hop-taking from under a third to over nine in ten. In production, about a third of queries now carry relevant material the flat search would have missed.
Read Article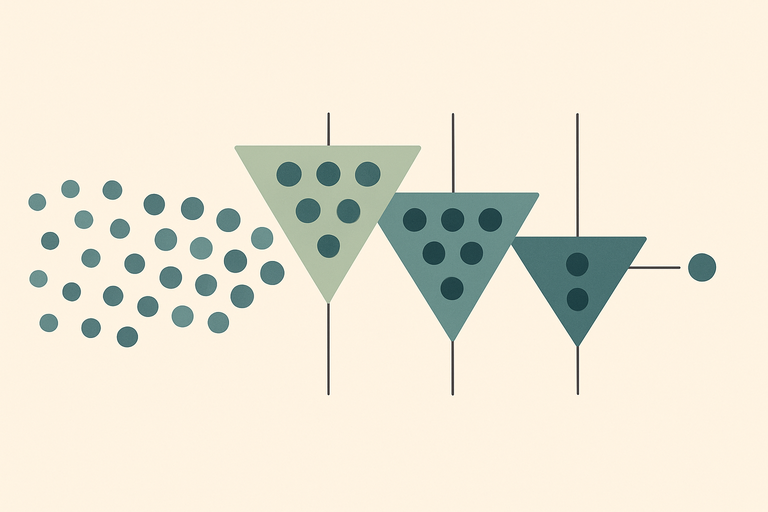
Ten Percent of Ten Percent: Why Independent Checks Beat Better Prompts
You will not prompt a language model step to zero errors, and the last few points cost more than everything before them. What works is a second check that fails differently from the first: 10% x 10% = 1%, but only when the layers are genuinely independent. Five kinds of layer we use in production (reviewer agents that cannot see the author's reasoning, deterministic CI gates, structural guards, blind evaluation against held-out truth, and a human who sees the one percent), one chain from agent-written code to production, the incident that taught us to add an orthogonal layer instead of strengthening the one that missed, and what every layer costs.
Read Article
Up, Sideways, Out: Giving an Agent Fleet an Org Chart
Three of our monitoring agents spent a week investigating the same incident without knowing it, because the only channel between them was a thirty-minute message queue and they sleep for hours at a time. The week we finished the three channels an agent org chart actually needs — severity-gated escalation upward, durable peer messaging sideways, and commissioned work outward — and what the fleet did with them in its first 48 hours: 28 messages, 10 threads, one week-old incident split into lanes in a single exchange, and a fix commissioned, shipped, and verified by four agents with one human at the merge.
Read Article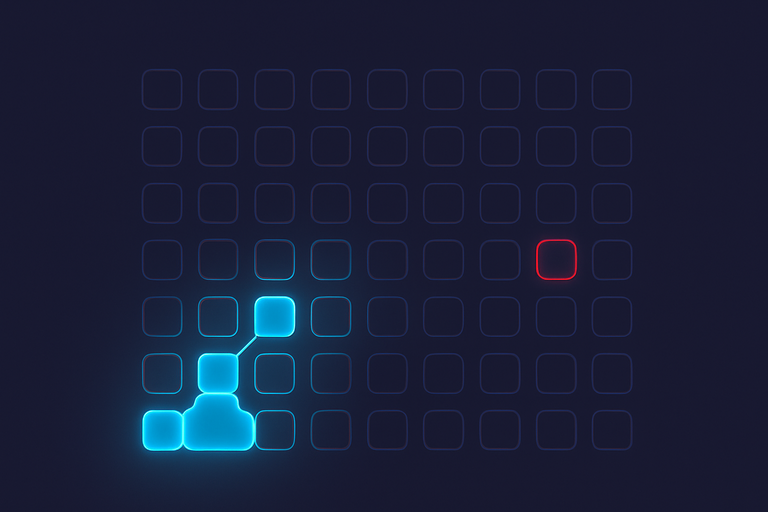
SESM: A State Machine That Teaches Itself
Start with 7 hand-written states. Let production traffic find the rest. A model that costs a hundredth of a cent per judgment does the triage — and a one-line rule keeps a 60%-accurate judge from ever corrupting the machine. Open source, with the receipts: blinded eval, convergence proof, and an interactive replay of a real run.
Read Article
The Dark Stair: We Asked Fable 5 to One-Shot a Game. It Did.
One prompt: 'one-shot an app — anything other than a final, polished, flawless product is a fail.' Fable 5 came back with a complete roguelike, no bugs, then iterated itself overnight to v7 — voice lines, sprites, Blender scenes, ambient music and all. Play it free, no signup.
Read Article
MCP-as-API-Wrapper: Inverting the MCP Pattern for Dynamic Agent Integration
The MCP-as-API-Wrapper pattern reduces the MCP server to a thin discovery and authentication layer with exactly three tools. The entire API surface evolves independently behind it.
Read Article
The Human Attention Bottleneck: Why the Next Leap in AI Isn't Smarter Models
The constraint on AI systems isn't intelligence anymore. It's us. Human attention has become the bottleneck, and the organizations that figure out how to systematically address this will define the next era of software.
Read Article